Best Serverless Security Best Practices
Learn serverless security best practices for IAM, event filters, resource limits, secret storage, vulnerability scans, logging, and monitoring.
Serverless removes server upkeep, but it doesn't remove security work. A leaked secret, broad function role, or oversized request can still open a path into your cloud account.
These serverless security best practices give you a working order: protect secrets first, narrow access, cap resource use, scan changes, then watch the evidence.
1. EnvManager
Start with EnvManager when your serverless security plan includes environment variables and API keys. EnvManager encrypts, version-controls, and centrally manages.envfiles. It also uses role-based access control, or RBAC, so each team member gets access based on their job.
This closes a common gap. IAM protects access to cloud services, but it doesn't replace a dedicated process for application secrets. A function may have a narrow role and still expose a database password through a copied file or a CI variable.
Use EnvManager as the source for local development and deployment pipelines. Keep secrets out of source control. Give developers the values they need without sending raw files through chat or email. When a value changes, update the managed version instead of asking every engineer to edit a local file by hand.
EnvManager can sync secrets to local machines and CI/CD pipelines. That gives your team one place to review which values exist and how they move into a deployment. Its version history also helps you trace a bad change during an incident.
If a static front end needs to call a service, don't place its private key in browser code. A server-side proxy keeps the key away from users, as shown in EnvManager's secure proxy functions workflow.
Set access by role. Review it when someone changes teams. Remove access when a project ends. No more mystery copies of production credentials sitting in old folders.
One caveat: secret management cannot fix an over-permissioned function. You still need cloud IAM controls, event filters, and runtime limits. Treat EnvManager as the first layer, not the whole security plan.
Step 2: Apply Least-Privilege IAM and Event Allowlists
Least-privilege IAM is one of the most important serverless security best practices because each function should have only the access it needs.
Begin with an inventory. Write down each function's purpose, trigger, data store, and outbound service calls. Then make a separate role for each function or small function group. Avoid one shared role that can read every bucket and call every service.
For a function that writes order data, allow the required write action on the required resource. Don't grant broad read access to unrelated data. If a function only reads one table, its role shouldn't manage tables across the account.
Use a short test cycle after each policy change:
- Run the function through its normal success path.
- Test a blocked action that the function should not need.
- Review denied requests before deployment.
- Record the owner and reason for each exception.
Identity rules apply to machine accounts too. A CI job, function, or scheduled task has credentials even when no person logs in. Give each workload its own identity so you can revoke one path without breaking the rest of the system.
Then filter events. A function should accept events from known sources, not any service that can reach its endpoint. Check the event type, source account, resource ID, and expected schema. Reject an event that fails those checks before it reaches business logic.
For API-facing functions, place authentication and authorization checks before expensive work. EnvManager's API key security guidance also covers short-lived access patterns and the risk of leaving keys in application code.
Cloud permissions can look correct on paper while the event path stays open. The secure API design guidance describes least-privilege roles, execution limits, event-source allowlists, and payload controls as separate safeguards. Use all four. One control rarely catches every bad request.
By now you should have one role per workload, a written owner, and an allowlist for every event source. Keep the policy narrow until a test proves that a wider rule is needed.
Step 3: Limit Payloads, Execution Time, and Resource Abuse
Resource limits give your serverless security work a hard edge. They stop a bad request from consuming an open-ended amount of memory, time, or downstream capacity.
Set a maximum request size at the edge. Reject large bodies before the function parses them or writes them to storage. The limit should match the real business need. A small lookup endpoint has no reason to accept a multi-megabyte upload.
Payload limits also need field checks. Confirm required fields. Reject unexpected types. Cap array length. Validate file names and content types. Do this before your function calls another service.
Set an execution timeout for every function. A timeout stops a stuck process from running until it consumes its full allocation. Keep it close to the longest valid request, then test slow dependencies and retry behavior.
Timeouts don't replace rate limits. Use throttling for public endpoints and quotas for expensive actions. A request that takes one second can still cause harm when an attacker sends thousands of them.
Watch fan-out too. One event may call several functions, which then call storage, queues, or external APIs. Put a cap on retries and set a dead-letter path for events that keep failing. Otherwise, a small error can turn into a large bill or a service outage.
Use this test case before release:
- Send a request just below the allowed size.
- Send one above the limit and confirm a fast rejection.
- Delay a dependency and confirm the timeout fires.
- Force repeated failure and confirm retries stop.
Run the test in a non-production account first. Then alert on unusual rejection rates, timeout spikes, and retry growth. Those signals often show abuse before an incident becomes obvious.
Step 4: Schedule Vulnerability Scans and Verify Urgent Fixes
Scheduled scans give serverless security programs a repeatable check, but a schedule alone isn't enough. Serverless code and dependencies can change between scan windows.
Start by discovering every workload. Include functions in development accounts, test regions, and short-lived deployment stacks. Record the function name, owner, runtime, source repository, environment, and data it can reach.
Assign a real owner to each workload. A blank owner field turns a high-risk finding into a queue item nobody can close. Use a team alias when individual ownership would go stale, but make one person responsible for the fix.
Scan on a defined cadence. Also scan when a dependency changes, a runtime changes, or a new function enters production. A weekly task may miss a serious issue in a fast-moving pipeline.
Prioritize findings by exposure and impact. A public function with access to customer data deserves faster action than an unused test function with no network path. Keep the reason for each exception in the ticket, along with its expiry date.
After a fix, run an on-demand scan. Don't wait for the next scheduled job to confirm that the vulnerable package, unsafe setting, or exposed function is clean. The second scan proves that the change reached the deployed workload.
Secret scans belong in the same workflow. Check source code, build logs, deployment packages, and configuration files. A key removed from code may still exist in Git history or an old artifact. Rotate it when exposure is possible, then confirm the replacement reached every needed environment.
EnvManager helps keep that rotation controlled because teams can update the managed value and sync it through approved paths. Its secrets management comparison also gives teams a way to assess storage, access, and deployment needs before choosing a workflow.
By now you should have an asset list, named owners, a scan schedule, and a short path for urgent fixes. A finding is not closed when someone changes a file. It is closed when the deployed workload passes verification.
Step 5: Monitor Events, File Integrity, and Centralized Logs
Monitoring turns serverless security best practices into evidence you can act on. You need to know what changed, which workload changed it, and who owns the next move.
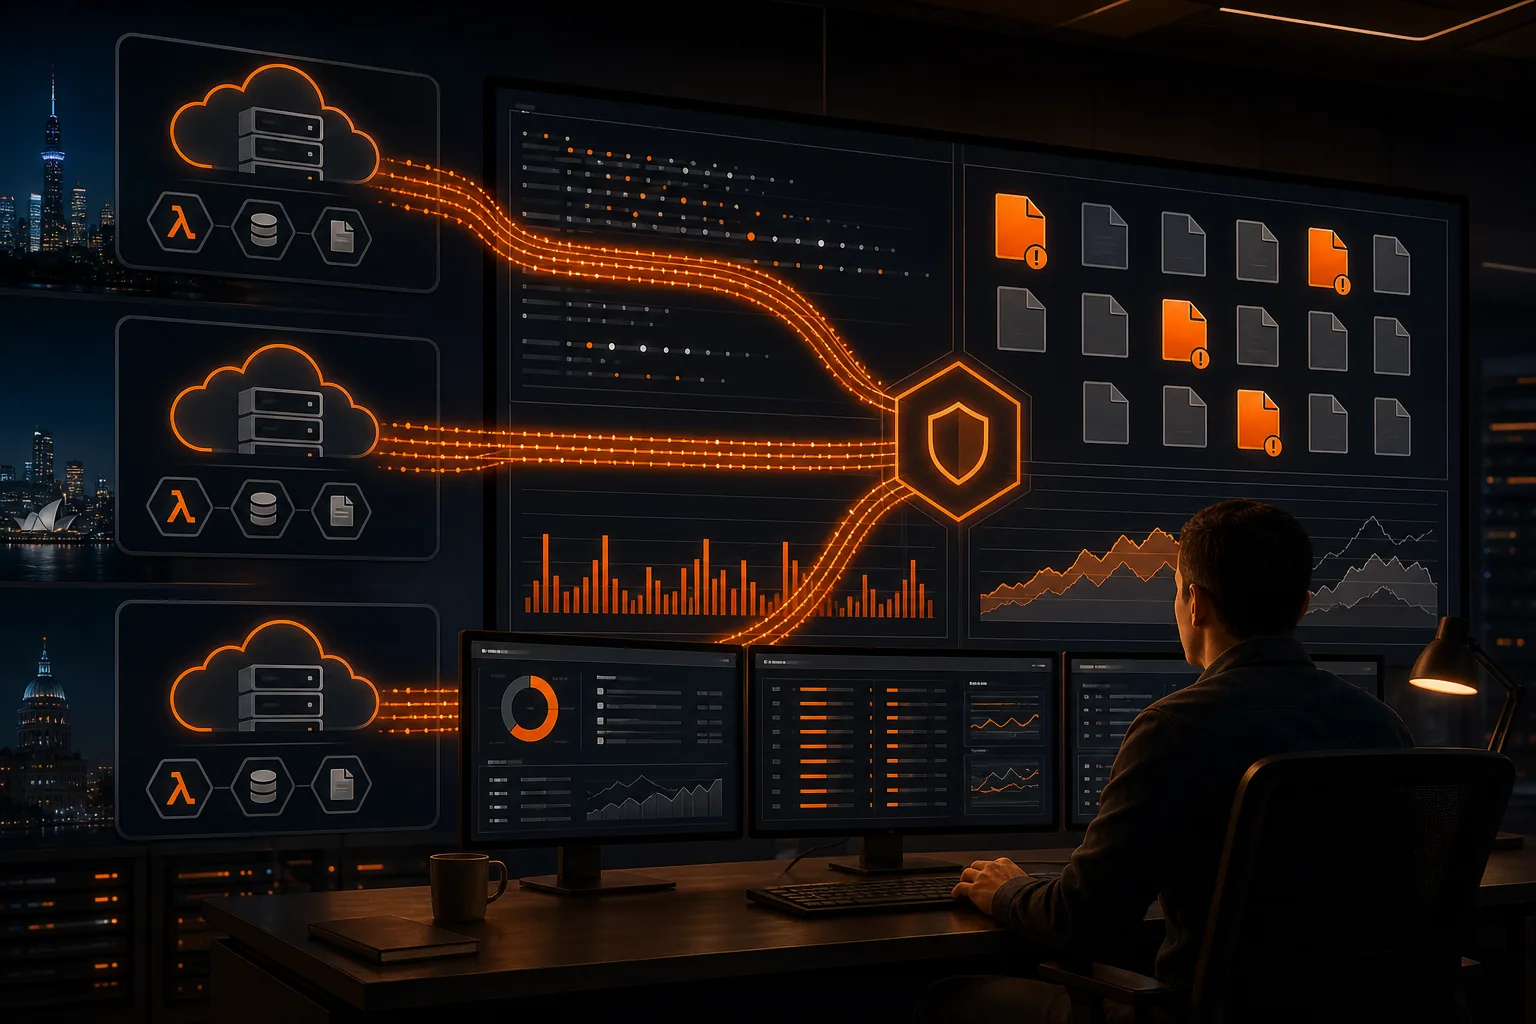
Collect function invocations, authentication failures, permission denials, configuration changes, and unusual outbound calls. Track both successful and failed actions. A stream of denied requests can reveal probing even when no request succeeds.
Watch host-level events where your architecture includes hosts, containers, or managed runtimes with host signals. A missing event source creates a blind spot during investigation. Test the collection path instead of assuming the console contains every record.
Use file-integrity monitoring for code packages and sensitive configuration. Alert when content or permissions change outside the deployment process. A change during a maintenance window may be valid, but it still needs an owner and a reason.
Centralize logs in one searchable repository. Scattered logs slow incident response because analysts must switch between cloud accounts, regions, and service consoles. A central view should preserve the event time, workload ID, environment, actor, and request link.
Cost control matters. Keep high-value security events at a level that supports investigation, while avoiding noisy debug output in production. Define retention by use case. Incident response needs recent detail, while audit needs a clear record of access and change.
A workload can pass a scan and drift later after a manual change. It is useful to connect the asset with its owner, event, control, ticket, and fix. That chain is more useful than another dashboard full of disconnected alerts.
Set alerts for a small set of high-signal changes first:
- A function gains a new permission.
- A deployment comes from an unapproved source.
- A sensitive file changes outside the release window.
- Repeated authentication failures target one endpoint.
- A workload loses its owner or environment tag.
Send each alert to a queue with a named response owner. If every alert goes to a shared channel, the team may see the problem and still fail to fix it.
Run a monthly evidence check. Pick one function and trace its owner, current role, recent events, deployment record, scan result, and open exceptions. If you can't complete that path, your monitoring is not ready for a serious incident.
FAQ
What are the most important serverless security best practices?
The most important practices are secret management, least-privilege IAM, event-source filtering, payload limits, execution timeouts, vulnerability scans, and centralized monitoring. Start with secrets and identity because they control access. Then add resource limits and logging so abuse is harder to trigger and easier to investigate.
How do you secure secrets in a serverless application?
Secure secrets by keeping them out of source code and browser bundles, then storing them in a controlled secret-management system. Use role-based access and approved CI/CD paths. Rotate exposed values quickly. EnvManager manages encrypted, version-controlled.envfiles and can sync them to local machines and deployment pipelines.
Why is least privilege important for serverless functions?
Least privilege limits what an attacker can reach if one function is compromised. Give each function a separate role with only the required actions and resources. Review denied requests during testing. This serverless security practice reduces the blast radius of a stolen credential or vulnerable dependency.
How can I prevent serverless denial-of-service attacks?
Prevent resource abuse by setting payload limits, execution timeouts, concurrency controls, rate limits, and retry caps. Reject oversized requests before they reach business logic. Test slow dependencies and repeated failures. These controls reduce the chance that one endpoint consumes excessive compute or triggers a costly retry loop.
How often should serverless functions be scanned?
Scan serverless functions on a defined schedule and after meaningful changes. Run an on-demand scan after fixing an urgent vulnerability. Include short-lived functions, test accounts, and new regions in your inventory. A scheduled scan finds known issues, while change-based scans reduce the gap between deployment and detection.
Conclusion
Use EnvManager to control application secrets, then narrow IAM roles and event sources. Add payload and timeout limits before release. Finally, connect scans, logs, and owners so every alert has a clear next step. Start with one production function today and trace its secret, role, limits, scan result, and recent events.
Implementation Checklist
- Store application secrets in EnvManager instead of source control.
- Assign one owner to every function and workload.
- Create a separate least-privilege role for each function.
- Allow only expected event sources and event types.
- Set request-size and execution-time limits.
- Cap retries, concurrency, and expensive downstream calls.
- Scan on schedule and after dependency or runtime changes.
- Verify urgent fixes with an on-demand scan.
- Monitor permission changes, failed access, and file changes.
- Send logs to one searchable location with clear retention rules.