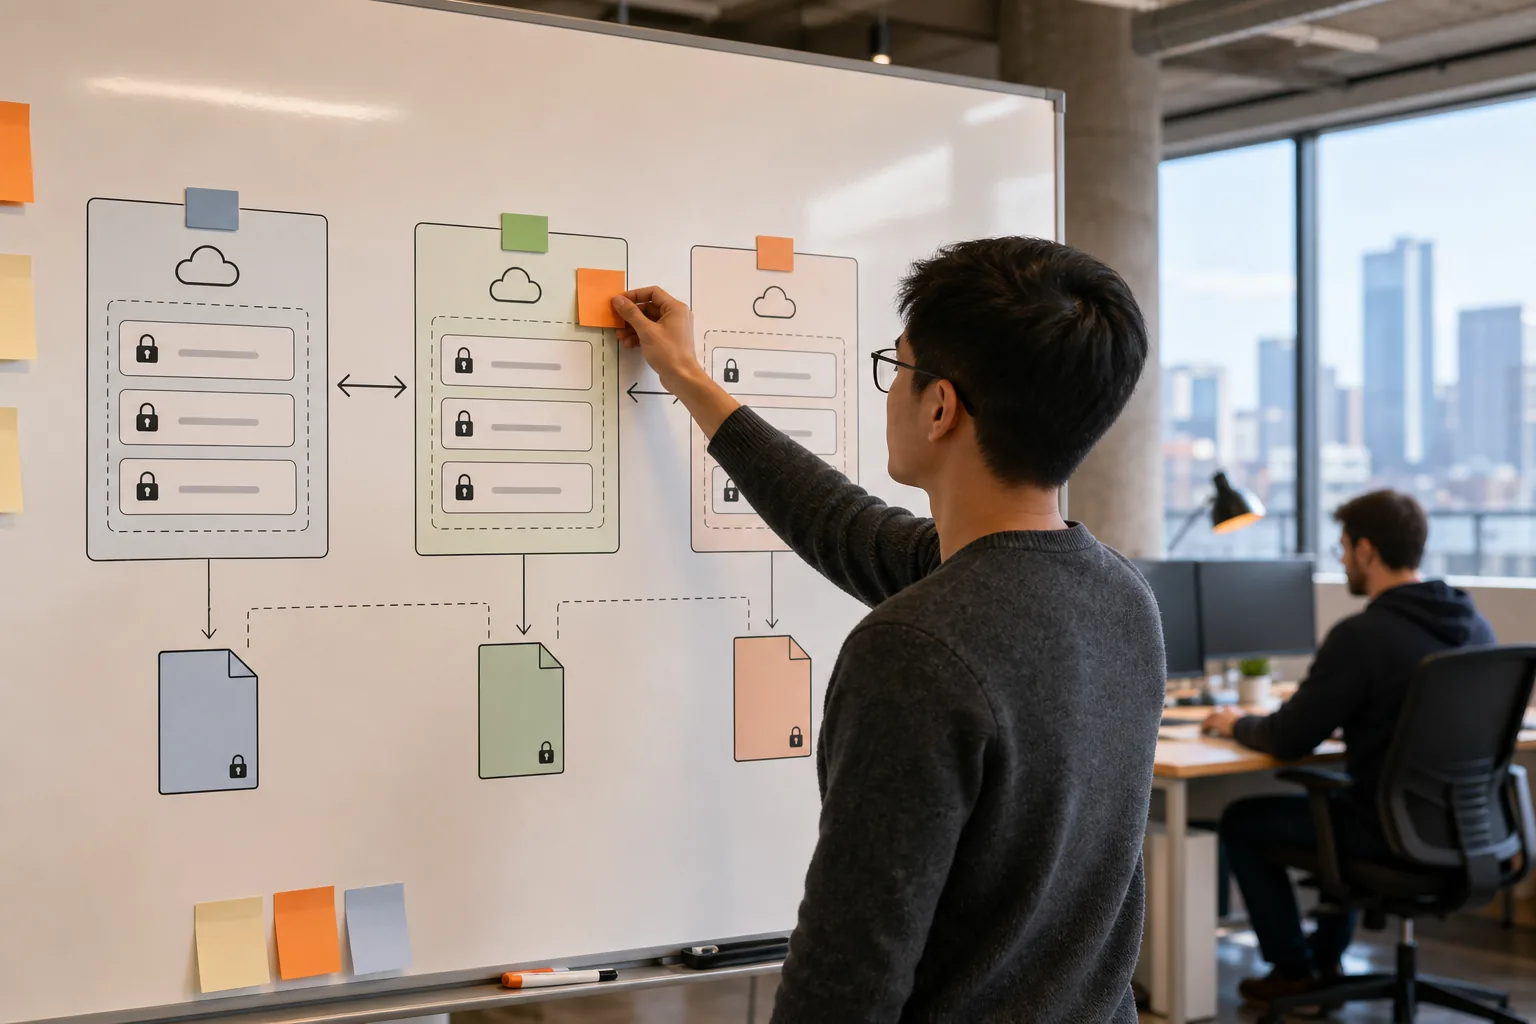
How to Set Per-Environment Access Control for .env Files
Set per-environment access control for .env files with clear permissions, safer local loading, centralized secrets, and a repeatable audit and rotation process.
A local .env file can feel like a private note, but anyone who can read it may get the same keys your app uses. Set a separate access rule for each environment, then make sure local files and deployment jobs only receive the secrets they need.
The key is to treat a .env file as a short-lived working copy, not the master store. Here’s a step-by-step way to set boundaries, tighten access, and reduce secret sprawl.
We pulled 3 public secrets datasets: a scan of 2.6 million domains for exposed.env files, and 2 GitGuardian State of Secrets Sprawl reports. The domain scan found 201 exposed.env files holding 135 database credential pairs, 98 API tokens, and 128 app secrets. GitGuardian's 2026 report counted 28.65 million hardcoded secrets on public GitHub in 2025, up 34% year over year. An earlier GitGuardian report put private repository exposure at 35% versus 4.6% for public repos, the gap access rules are meant to close.
Step 1: Inventory Secrets and Define Environment Boundaries
Per-environment access control starts with knowing what each file contains and what it can reach. A staging database password and a production signing key should not live in one shared file.
Start by listing each project and its environments: local development, shared development, staging, and production. For every variable, note its purpose, owner, environment, and the service it protects. Mark which values are secrets, such as database credentials or API tokens, and which are ordinary settings, such as a log level.
Next, compare the files on developer laptops with the values stored in CI settings and deployment dashboards. Look for duplicate keys with different values. That mismatch can make a test point at a production service, or leave a revoked key in an old local file.
Use a separate credential set for each environment wherever the service allows it. Set a rule that production secrets don’t flow into development or staging. Developers can test with a staging key without receiving a production credential they don’t need.
Write down who needs access and what they need to do. A developer may need read access to staging. A release process may need to read production values during deployment. A reviewer may need to see a change history without being able to change a secret. These decisions should follow access control best practices, including least privilege and environment isolation.
As you prepare the inventory, keep secret files out of source control. Ignore-file patterns can exclude untracked files from Git’s normal file list. Add the relevant .env patterns to .gitignore, but don’t treat that rule as a permission check or a way to remove a secret already committed.
The inventory gives you a clear scope for each permission. EnvManager can keep encrypted, versioned environment values in one place, with role-scoped access for development, staging, and production. That gives the team a central record to work from instead of relying on whoever has the newest local copy.
Step 2: Apply Least-Privilege Access to Local .env Files
Per-environment access control only works if local files have a clear owner and limited readers. A shared laptop account or a file readable by every local user can undo the rules in your secret store.
First, keep each local .env file out of the repository. Add project-specific files such as .env.local to .gitignore. Commit a template such as .env.example with variable names and safe placeholder text, never real values. Check Git’s tracked files before you push; an ignore rule won’t remove a file that Git already tracks.
Then check ownership and file permissions on the machine. On a Unix-style system, set the file so only its owner can read and write it:
chmod 600 .env.localConfirm the change with ls -l .env.local. The permission digits mean the owner can read and write, while the group and other local users get no access. Set the right owner as well, especially if a container or local service runs under a different account.
Use access control lists only when the work needs them. For example, a service account may need read access to one file while a developer account owns it. Grant access to that specific identity, then test from another account to make sure the file is denied. On systems that use SELinux or AppArmor, review the policy for the process that loads the file; Unix file bits don’t replace those controls.
Keep files out of shared folders, shell history, screenshots, and support tickets. Don’t paste a full secret into a chat to help someone debug a connection. Share the variable name and error message instead, then grant short-lived access through the approved secret store if the other person needs the value.
Think about tools that can read your project folder, too. AI coding assistants may use files as context, and ignore rules may not stop an agent from running a shell command that reads a local file. Keep secrets outside the workspace when possible, or use a managed flow that supplies them only when the application runs.
For a team, role-based access control means permissions follow a person’s work rather than informal file sharing. EnvManager supports role-scoped access across environments. Its plain-language explanation of RBAC can help your team define roles before you assign them.
Check the denial path: test that a developer who only needs staging cannot read production, both in the central system and on a machine that holds a local file.
Step 3: Load the Right Environment File in Local Development and Containers
Safe loading keeps the correct environment’s values out of code and limits what a process can see. The per-environment access rule needs to carry through local development, container setup, and CI.
For local work, use one documented command to load the intended environment. If your app reads a local file, name it clearly and keep it out of Git. Don’t rely on a developer remembering which file to copy before running a test. A wrong copy can send a local command to a live database.
For a development container, pass the selected file at startup rather than baking secrets into the image. With Docker’s run command, the --env-file option supplies variables from a file when the container starts. Keep the file on the host and out of the build context.
For a container setup that uses run arguments, configure it to load the intended environment file. Use a full path where the setup calls for one, then rebuild and verify that the process sees the expected values. Don’t assume a variable available on your host automatically exists inside the container.
Validate the active environment at startup. One useful check is to require a non-secret environment label, such as APP_ENV=staging, and fail if it conflicts with the selected secret set. Avoid printing secret values during checks. A log line that says “DATABASE_URL is set” is safer than logging its full contents.
In CI, fetch values for the job’s target environment only. A staging test job should not have a production token in its process environment. Split test and deploy jobs when their secret needs differ, and limit each identity to the relevant project and environment.
EnvManager supports syncing environment values to local machines and CI/CD pipelines, so teams can use a consistent handoff instead of copying secrets by hand. One simple local workflow can be:
envmanager pull
npm run dev
For a deployment, name the target environment in the pull step and run only the commands that need those values. Review the command’s output and pipeline logs to ensure they don’t reveal secret contents.
Step 4: Move Shared and Production Secrets to Centralized Management
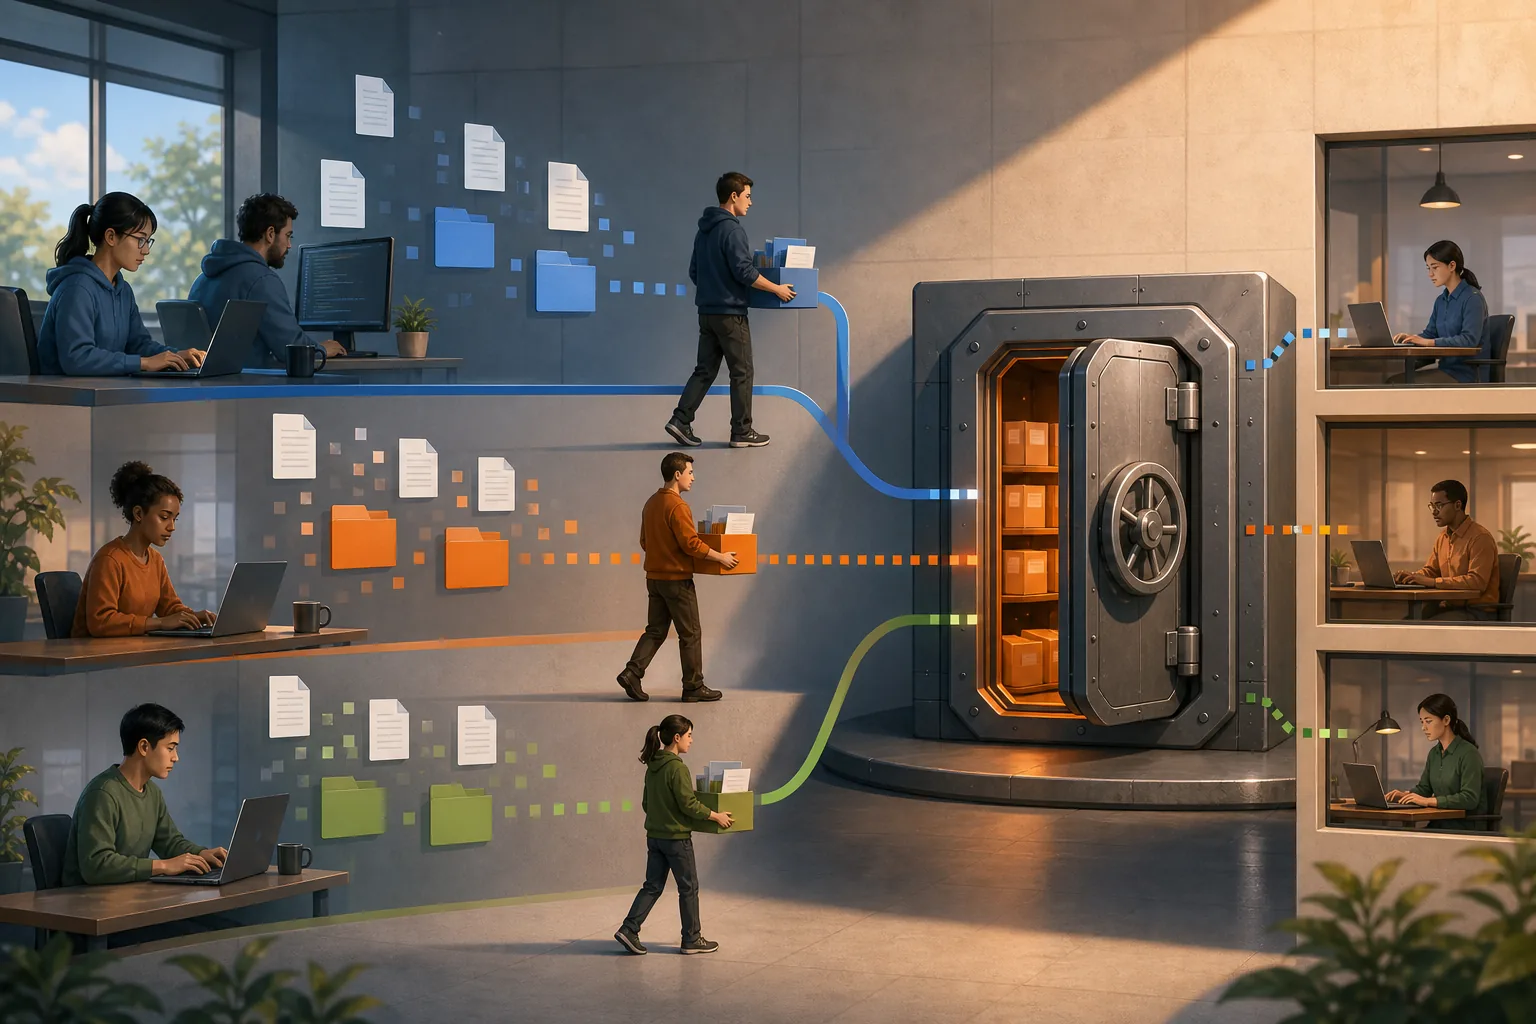
Centralized secret management gives your environment boundaries one place to live. It replaces email attachments, chat pastes, and long-lived shared files with controlled access to a current version.
Choose a system that can separate projects and environments, set access by role, and show who changed or read a secret. Check how developers and CI retrieve values. If the workflow requires manual copying for every handoff, people may keep old files as a workaround.
Move one project first. Import its current values, sort them by environment, and check each value with its owner. Set permissions before inviting the whole team. Then update local setup and CI to fetch the right environment. After the new path works, remove old files and revoke credentials that were copied into them.
For production, make access narrower than it is for development. Most developers don’t need direct access to live credentials for daily work. A deployment identity can retrieve only the values needed for a specific service, while a responder can receive temporary access during an incident.
EnvManager encrypts values on import and keeps versions, so teams can manage the current set from a shared system. It also supports role-based access across development, staging, and production. That can make a handoff easier to review: a developer gets staging access for a test, while production remains restricted to the identities that deploy or respond.
Before migration is complete, test both a permitted and denied request. Confirm a staging user can load staging values. Then confirm that the same identity cannot read production. Removing the old plaintext copies matters too; a central vault does not protect credentials that remain in a shared drive or a forgotten laptop file.
Step 5: Audit Access, Rotate Secrets, and Reduce Accidental Exposure
Auditing shows whether per-environment access control is working after setup. A useful record connects an identity to an action, a secret set, and an environment.
Review access events and changes on a regular schedule. Look for unexpected reads, permission updates, and secrets that no longer have an owner. When an engineer changes teams or leaves, remove their access promptly and check machine identities too. A build bot can keep access long after the person who created it has moved on.
EnvManager maintains audit trails and versioned secret changes. Its RBAC limits access by role, and its environment scope helps distinguish a staging action from a production one. That record can help during an incident review because a team can trace changes instead of guessing which local copy was used.
Plan rotation before a key leaks. First, create a replacement credential with the same narrow scope. Store it in the managed system, then update the application or pipeline. Verify that the new value works before revoking the old one. If the provider supports a dual-key handoff, use it to avoid an outage during the switch.
Don’t claim that every secret can rotate automatically. Some systems support workflow-driven rotation, while others require a human or custom integration to make and verify the change. Check the source service’s rotation behavior, then record the owner and expected process for each credential.
A suspected leak changes the order: revoke or disable the exposed credential first. Then replace it, check service logs for unexpected use, and remove the value from any old copies. Deleting a secret from Git history may reduce later exposure, but it does not make the leaked credential safe again.
AI coding tools add another reason to keep secrets out of project folders. A project ignore file can reduce passive indexing, but an agent with shell access may still read a file. The research source on AI coding agents and secret exposure describes this limit. Prefer runtime injection when possible, and check your tool’s own data and access settings.
Rotation is only useful when it reaches every place that uses the key. After replacing it, check the application, CI jobs, container settings, and any local copies your team still supports. If one old consumer fails, fix that path before treating the rotation as complete.
FAQ
How do I keep .env files out of Git?
Add the relevant .env patterns to .gitignore before creating local secret files, and commit a safe .env.example template instead. Check whether Git already tracks a file, because ignore rules don’t untrack it. If a secret was committed, revoke or rotate it first; removing it from the latest commit does not undo exposure in history or copies.
Should development and production use the same .env file?
No. Use separate credentials and access rules for each environment. If a developer needs staging access, that should not grant access to production by default. Keep the selected environment clear in local commands and deployment jobs, then verify that a staging identity cannot retrieve production values.
How can I restrict who reads a local .env file?
Set the file owner and operating-system permissions so only the needed user or service can read it. On Unix-style systems, chmod 600 .env.local is a common starting point for a file owned by the current user. For teams, per-environment access control should also be enforced in a central secret manager, not only on each laptop.
Can Docker load variables from a .env file?
Yes. Docker’s run command supports an --env-file option to pass values into a container at startup. Keep the file out of the image and build context, and choose the file for the target environment. Check logs and container settings so secret values don’t appear in output or get copied into an image layer.
Do AI coding tools read .env files?
They may, depending on the tool and how it accesses your project. Ignore settings can help with passive indexing, but they may not block an agent that can run shell commands. Keeping secrets out of the workspace is a stronger boundary. If that isn’t possible, review the tool’s file exclusions and test what it can access.
Conclusion
Keep separate credentials for each environment, enforce access centrally, and treat local .env files as temporary copies. Start by inventorying one project, then move its secrets into EnvManager and test both allowed and denied access before repeating the process for another service.